Executive Overview
The landscape of Artificial Intelligence has evolved dramatically, yet organizations frequently encounter a stubborn bottleneck: the "document comprehension gap." Standard Retrieval-Augmented Generation (RAG) architectures have traditionally excelled at digesting plain, unformatted text. However, when fed real-world business assets—such as complex PDF documents packed with embedded charts, scanned architectural diagrams, and dense financial data tables—these traditional systems break down rapidly. Traditional text-based chunking mechanisms destroy underlying table formatting, bypass critical images entirely, and deliver answers derived from an incomplete, text-only picture of the source document.
This architectural limitation leaves modern enterprises vulnerable to missed insights and hallucinated outputs. Enter the Multi-Modal Retrieval-Augmented Generation (RAG) pipeline—a sophisticated paradigm shift that treats visual artifacts (images, tables, and schematics) as first-class, retrievable objects alongside textual prose.
In this exhaustive technical guide, we explore how to construct a robust, production-ready multi-modal RAG pipeline in Python. By leveraging industry-standard tools including LangChain, the Unstructured library, Chroma, and the OpenAI API (specifically GPT-4o), developers can parse complex documents into distinct modalities, generate highly searchable text summaries for visual elements, implement a multi-vector retrieval system, and query multimodal assets to generate precise, grounded insights.
Detailed Chronology and Technical Architecture
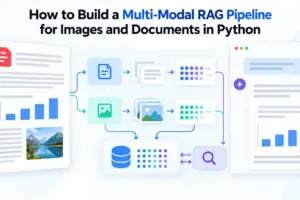
Designing a modern multi-modal RAG pipeline requires a deliberate, multi-staged engineering approach. Rather than dumping raw files into a single flat vector database, an enterprise-grade solution processes documents across four distinct architectural phases: Parsing, Summarization, Storage, and Multimodal Retrieval.
Step 1: Parsing Complex Documents into Text and Image Elements
The primary challenge in document ingestion is semantic separation. PDFs and corporate reports blend prose, headers, data tables, and diagrams into a single binary stream. Standard parsers flatten this data, destroying context.
To overcome this, we utilize the unstructured library, which applies advanced layout parsing to classify document elements by type. The code below illustrates how to execute a partition on a complex PDF file:
from unstructured.partition.pdf import partition_pdf

raw_elements = partition_pdf(
    filename="report.pdf",
    extract_image_block_types=["Image"],
    extract_image_block_output_dir="./extracted_images",
    infer_table_structure=True,
    chunking_strategy="by_title",
    max_characters=4000,
)
By configuring parameters such as infer_table_structure=True and specifying extract_image_block_output_dir, the parser isolates visual blocks and saves them to disk while preserving structural text chunks. Next, we segregate these raw elements into distinct text and image lists for downstream processing:
text_elements = []
image_paths = []

for el in raw_elements:
    if "CompositeElement" in str(type(el)):
        text_elements.append(str(el))
    elif "Image" in str(type(el)):
        image_paths.append(el.metadata.image_path)

print(f"Extracted len(text_elements) text chunks, len(image_paths) images")
Step 2: Generating Searchable Summaries for Visual Artifacts
Standard text vector databases cannot natively index raw image files. To make images searchable via natural language queries, we must generate a semantic text proxy. This is achieved by passing every extracted image to a vision-capable Large Language Model—specifically GPT-4o—prompted to produce dense, contextual descriptions.
First, initialize the OpenAI client:
import base64
from openai import OpenAI

client = OpenAI()
Next, define a helper function that base64-encodes each extracted image file and submits it to GPT-4o for a high-fidelity semantic description:
def summarize_image(image_path):
    with open(image_path, "rb") as f:
        image_data = base64.b64encode(f.read()).decode("utf-8")

    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[
            "role": "user",
            "content": [

                    "type": "image_url",
                    "image_url": "url": f"data:image/png;base64,image_data"
                ,

                    "type": "text",
                    "text": "Describe this image in detail for use in a search system."

            ]
        ]
    )
    return response.choices[0].message.content

# Generate summaries across all extracted images
image_summaries = [summarize_image(p) for p in image_paths]
These generated summaries act as searchable proxies in our vector index, while the raw image files are securely stored separately, waiting to be retrieved by direct reference.
Step 3: Constructing the Multi-Vector Store Architecture
Traditional RAG architectures couple the vector embedding directly to the retrievable content chunk. Multi-modal RAG decouples this relationship via a MultiVectorRetriever.
This component maintains two decoupled stores:
- A Vector Store (Chroma): Stores embedded text chunks and image summaries to facilitate high-speed similarity search based on user queries.
- A Document Store (InMemoryStore): Holds the raw source content (both original text and raw image paths) linked to the embeddings via unique Universally Unique Identifiers (UUIDs).
import uuid
from langchain_openai import OpenAIEmbeddings
from langchain_chroma import Chroma
from langchain.storage import InMemoryStore
from langchain.retrievers.multi_vector import MultiVectorRetriever
from langchain_core.documents import Document

embeddings = OpenAIEmbeddings(model="text-embedding-3-small")
vectorstore = Chroma(embedding_function=embeddings)
docstore = InMemoryStore()

retriever = MultiVectorRetriever(
    vectorstore=vectorstore,
    docstore=docstore
)

text_ids = [str(uuid.uuid4()) for _ in text_elements]
image_ids = [str(uuid.uuid4()) for _ in image_summaries]
With our storage infrastructure initialized, we populate both stores, ensuring seamless relational mapping:
# Add summaries and text chunks to the vector search index
retriever.vectorstore.add_documents(
    [
        Document(page_content=t, metadata="doc_id": i)
        for t, i in zip(text_elements + image_summaries, text_ids + image_ids)
    ]
)

# Map unique IDs to raw source documents in the document store
raw_docs = (
    [Document(page_content=t, metadata="type": "text") for t in text_elements] +
    [Document(page_content=p, metadata="type": "image") for p in image_paths]
)

retriever.docstore.mset(list(zip(text_ids + image_ids, raw_docs)))
Step 4: Querying the Multimodal Pipeline
When a user submits a query, the retriever embeds the question, scans the vector store for the closest semantic matches (whether originating from prose or an image summary), and fetches the corresponding raw assets from the document store.
The pipeline then bundles these heterogeneous assets into a unified multimodal payload for GPT-4o:
def query_pipeline(question):
    docs = retriever.invoke(question)
    text_content, image_content = [], []

    for doc in docs:
        if doc.metadata.get("type") == "image":
            with open(doc.page_content, "rb") as f:
                img_b64 = base64.b64encode(f.read()).decode("utf-8")
            image_content.append(
                "type": "image_url",
                "image_url": "url": f"data:image/png;base64,img_b64"
            )
        else:
            text_content.append(
                "type": "text",
                "text": doc.page_content
            )

    # Assemble multimodal prompt context
    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[
            "role": "user",
            "content": text_content + image_content + ["type": "text", "text": question]
        ]
    )
    return response.choices[0].message.content

# Execute a query targeting visual financial data
answer = query_pipeline("What does the revenue chart show for Q3?")
print(answer)
Supporting Context & Quantitative Metrics
Implementing a multi-modal pipeline introduces distinct operational trade-offs that systems architects must carefully calculate.
| Pipeline Component | Computational Overhead | Primary Cost Factor | Accuracy Impact |
|---|---|---|---|
| Standard Text RAG | Low | Embedding API Calls | Poor on complex PDFs/Charts |
| Multi-Modal RAG (API-Driven) | Moderate-High | GPT-4o Vision API Calls | High across mixed media documents |
| Local Multimodal (e.g., ColPali) | Very High | Local VRAM / GPU Compute | Maximum layout fidelity |
Cost Optimization Strategies
- Image Filtering: Enterprise documents often contain dozens of decorative icons, low-value logos, and formatting dividers. Passing every extracted graphic to GPT-4o for summarization drives up API costs unnecessarily. Implementing a strict minimum file-size threshold (e.g., filtering out images under 10KB) drastically reduces inference expenditure during the indexing phase.
- Embedding Selection: Utilizing efficient text-embedding models like OpenAI’s
text-embedding-3-smallfor vector similarity matching keeps indexing overhead minimal while maintaining robust semantic retrieval performance over generated image descriptions.
Official Statements and Industry Alignment
Industry analysts and foundational AI research continue to validate the transition toward native multimodal intelligence. As highlighted in comprehensive sector studies such as The Multimodal AI Guide on KDnuggets, modern artificial intelligence frameworks are steadily abandoning siloed modality processing in favor of native cross-modal reasoning.
Furthermore, enterprise development teams are choosing between local, heavy-weight PyTorch architectures—ideal for audio, video, and massive vision-heavy workloads—and API-driven architectures (such as the LangChain-Unstructured stack outlined in this guide). API-driven pipelines offer a compelling advantage for business environments: they run efficiently on standard, cost-effective hardware while seamlessly scaling to process intricate multi-format enterprise assets.
Future Outlook & Production Hardening
While the four-stage pipeline presented here establishes a robust foundation for handling complex corporate documents, production environments demand further hardening and optimization.
Future engineering roadmap considerations include:
- Advanced Re-Ranking: Integrating cross-encoder re-rankers (such as Cohere Rerank) following the initial retrieval phase to drastically sharpen retrieval precision before passing documents to the generative model.
- Persistent Storage Solutions: Migrating the ephemeral in-memory Chroma vector database to a persistent, distributed disk storage configuration or enterprise vector engine (such as Pinecone or Milvus) to support high-availability production workloads.
- Native Vision-Language Models: Exploring emerging end-to-end vision-language architectures like ColPali, which bypass traditional text-summarization parsing steps altogether by directly embedding full document pages as visual embeddings.
By mastering the multi-modal RAG pattern, developers can bridge the gap between unstructured visual business assets and advanced generative reasoning, unlocking unprecedented value from enterprise data repositories.