
Tag: inference
From ZizzMedia, the free news encyclopedia
6 articles in this section
-
 Executive Overview The deployment of Large Language Models (LLMs) at enterprise scale faces a relentless, structural bottleneck. While hardware accelerators like the NVIDIA H100 GPU achieve phenomenal theoretical performance for matrix math, they sit largely idle during standard autoregressive text...
-
 Executive Overview The deployment of Large Language Models (LLMs) at enterprise scale faces a silent, structural crisis. While foundation models have achieved astonishing capabilities in reasoning, synthesis, and code generation, their deployment is hamstrung by a fundamental operational bottleneck: autoregressive...
-
 Executive Overview The deployment of Large Language Models (LLMs) at enterprise scale faces a formidable, persistent bottleneck: the autoregressive generation loop. Every time an enterprise application, coding assistant, or customer service agent invokes an AI chatbot, the underlying model must...
-
 Executive Overview The deployment of Large Language Models (LLMs) and transformer architectures has transitioned from an academic pursuit to a cornerstone of modern software engineering. However, developers transitioning from training transformer models in PyTorch to running them in production frequently...
-
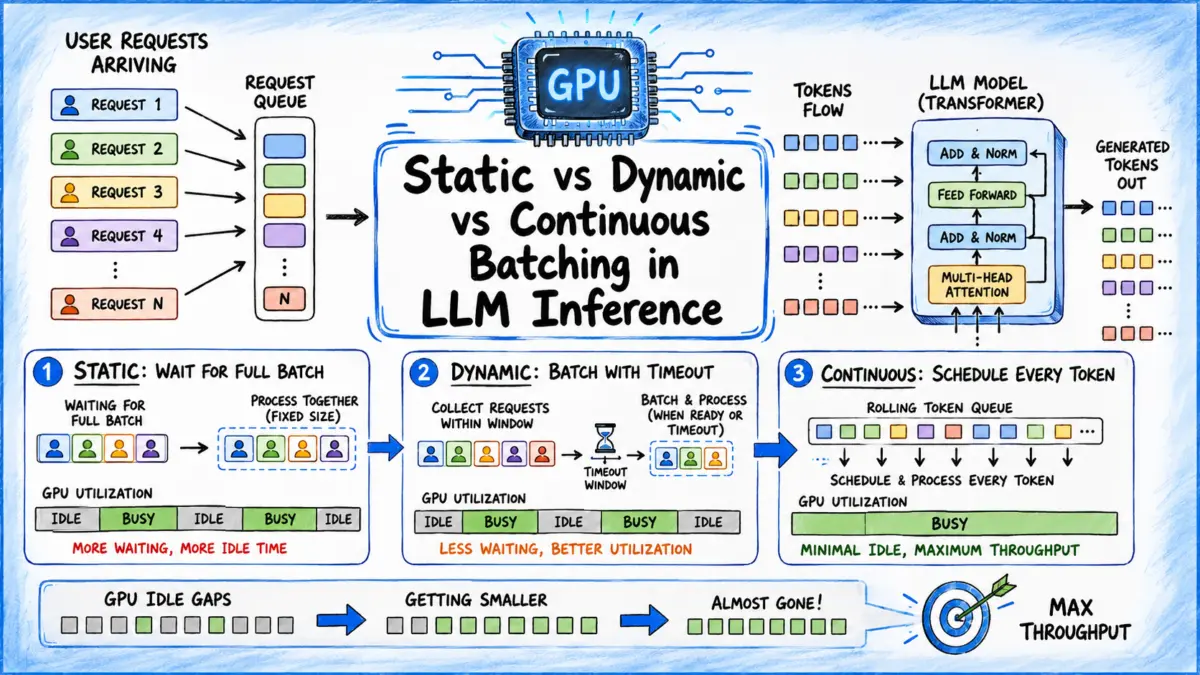 Executive Overview The commercial deployment of Large Language Models (LLMs) has ushered in an era of unprecedented computational demand. Behind the polished application programming interfaces (APIs) of generative AI assistants, enterprise search tools, and autonomous coding agents lies a brutal...
-
 Executive Overview In the rapidly evolving landscape of artificial intelligence, optimizing large language model (LLM) inference performance is no longer merely a niche pursuit for systems engineers—it is a critical economic and architectural imperative. However, attempting to optimize an LLM...