Executive Overview
For years, Retrieval-Augmented Generation (RAG) has served as the bedrock for grounding large language models (LLMs) in proprietary or domain-specific data. By converting text documents into vector embeddings and storing them in specialized databases, applications could successfully query corporate handbooks, policy manuals, and academic papers. However, traditional RAG carries a fatal flaw: it is fundamentally text-blind to the rich visual components of modern documents.
When fed a PDF packed with embedded financial charts, scanned architectural diagrams, complex data tables, or marketing graphics, traditional text-based chunking mechanisms inevitably fail. They destroy table layouts, discard embedded images, and reduce multi-dimensional visual payloads into disjointed strings of characters. The result is a system operating with an incomplete, severely hobbled picture of the underlying document.
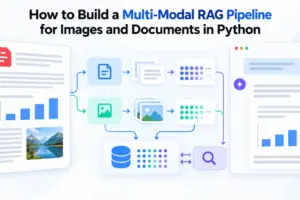
Enter the Multi-Modal RAG Pipeline—an advanced architecture that treats images as first-class retrievable objects alongside traditional text. By bridging the gap between text embeddings and visual perception using modern frameworks like LangChain, the unstructured library, and OpenAI’s GPT-4o, developers can now build robust enterprise systems capable of reading, parsing, reasoning over, and answering queries based on every element of a complex document.
This guide provides a comprehensive, step-by-step technical blueprint for engineering a production-ready, API-driven multi-modal RAG pipeline in Python. Designed to run efficiently on standard hardware, this architecture aligns seamlessly with modern business requirements, transforming static, multi-format documents into dynamic, fully comprehensible knowledge bases.
Detailed Chronology & Implementation Architecture
Building a multi-modal RAG pipeline requires a deliberate, four-stage architectural flow: Parsing, Summarization, Vector Storage, and Multi-Modal Retrieval. Below is the chronological blueprint for orchestrating these components from scratch.
Prerequisites and System Setup
Before writing any Python logic, you must ensure your local environment or server contains the necessary system libraries. Specifically, the unstructured library relies on system-level PDF processing utilities to reliably extract visual assets.
Execute the following commands to install the required Python packages and system dependencies:
pip install langchain langchain-openai unstructured[pdf] chromadb pillow
apt-get install -y poppler-utils
Next, configure your OpenAI API key within your execution environment. This key will power both the image summarization phase (using GPT-4o) and the downstream text embedding and generation tasks:
import os

os.environ["OPENAI_API_KEY"] = "your-api-key-here"
Step 1: Parsing Complex Documents into Text and Image Elements
The foundation of any robust RAG pipeline is ingestion. Standard PDF parsers strip out styling and ignore visual content, but the unstructured library provides an advanced partition_pdf() function that classifies document elements by semantic type. It carefully separates prose paragraphs, structured data tables, and embedded raster images.
from unstructured.partition.pdf import partition_pdf

raw_elements = partition_pdf(
    filename="report.pdf",
    extract_image_block_types=["Image"],
    extract_image_block_output_dir="./extracted_images",
    infer_table_structure=True,
    chunking_strategy="by_title",
    max_characters=4000,
)
In this configuration, extract_image_block_output_dir designates the filesystem destination for extracted image assets, while extract_image_block_types targets visual blocks. Once partitioned, we must separate the raw elements into clean, iterable text and image collections:
text_elements = []
image_paths = []

for el in raw_elements:
    if "CompositeElement" in str(type(el)):
        text_elements.append(str(el))
    elif "Image" in str(type(el)):
        image_paths.append(el.metadata.image_path)

print(f"Extracted len(text_elements) text chunks, len(image_paths) images")
Step 2: Generating Searchable Summaries for Embedded Images
Standard vector databases cannot index raw image binaries directly. To make an image searchable via natural language, we must generate a text proxy—a dense, descriptive summary that captures its visual information.
We accomplish this by passing each extracted image file to GPT-4o with a specialized, retrieval-focused prompt.
import base64
from openai import OpenAI

client = OpenAI()

def summarize_image(image_path):
    with open(image_path, "rb") as f:
        image_data = base64.b64encode(f.read()).decode("utf-8")

    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[

                "role": "user",
                "content": [

                        "type": "image_url",
                        "image_url":
                            "url": f"data:image/png;base64,image_data"
                        ,
                    ,

                        "type": "text",
                        "text": "Describe this image in detail for use in a search system.",
                    ,
                ],

        ],
    )
    return response.choices[0].message.content

# Generate summaries for all extracted images
image_summaries = [summarize_image(p) for p in image_paths]
Each generated summary acts as a searchable proxy for its corresponding image. Meanwhile, the raw image file is safely stored on disk, ready to be retrieved by reference when a query matches its textual proxy.
Engineering Note: Because every extracted image triggers a GPT-4o API call during ingestion, developers handling massive document libraries containing corporate logos or icons should implement a minimum file size or dimension filter prior to calling summarize_image().
Step 3: Constructing the Multi-Vector Store
Traditional RAG employs a single vector store where chunks map directly to themselves. Multi-modal RAG utilizes a MultiVectorRetriever, which manages two distinct underlying repositories:
- A Vector Store: Holds embedded text chunks and image summaries to maximize semantic search accuracy.
- A Document Store (Key-Value Store): Holds the raw source content (text strings or image file paths) linked to vector embeddings through unique Universally Unique Identifiers (UUIDs).
import uuid
from langchain.storage import InMemoryStore
from langchain_chroma import Chroma
from langchain_core.documents import Document
from langchain_openai import OpenAIEmbeddings
from langchain.retrievers.multi_vector import MultiVectorRetriever

embeddings = OpenAIEmbeddings(model="text-embedding-3-small")
vectorstore = Chroma(embedding_function=embeddings)
docstore = InMemoryStore()

retriever = MultiVectorRetriever(vectorstore=vectorstore, docstore=docstore)

text_ids = [str(uuid.uuid4()) for _ in text_elements]
image_ids = [str(uuid.uuid4()) for _ in image_summaries]
With our storage architecture initialized, we populate both stores, binding summaries to embeddings in the vector space while preserving raw content in the document store:
retriever.vectorstore.add_documents(
    [
        Document(page_content=t, metadata="doc_id": i)
        for t, i in zip(text_elements + image_summaries, text_ids + image_ids)
    ]
)

raw_docs = [
    Document(page_content=t, metadata="type": "text") for t in text_elements
] + [
    Document(page_content=p, metadata="type": "image") for p in image_paths
]

retriever.docstore.mset(list(zip(text_ids + image_ids, raw_docs)))
Step 4: Executing Multi-Modal Queries
At query time, the retriever embeds the user’s question, scanning both text chunks and image summaries simultaneously. When a match points to an image identifier, the pipeline loads the raw image file from disk, base64-encodes it on the fly, and packages it alongside retrieved text blocks for downstream reasoning by GPT-4o.
def query_pipeline(question):
    docs = retriever.invoke(question)
    text_content, image_content = [], []

    for doc in docs:
        if doc.metadata.get("type") == "image":
            with open(doc.page_content, "rb") as f:
                img_b64 = base64.b64encode(f.read()).decode("utf-8")
            image_content.append(

                    "type": "image_url",
                    "image_url": "url": f"data:image/png;base64,img_b64",

            )
        else:
            text_content.append("type": "text", "text": doc.page_content)

    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[

                "role": "user",
                "content": text_content
                + image_content
                + ["type": "text", "text": question],

        ],
    )
    return response.choices[0].message.content

# Execute a sample query targeting visual data
answer = query_pipeline("What does the revenue chart show for Q3?")
print(answer)
Supporting Context & Metrics
The transition from text-only RAG to multi-modal architectures is not merely aesthetic; it is driven by empirical performance improvements in enterprise environments:
- Information Density in Modern Documents: Industry analyses indicate that upwards of 35% of critical business data in technical manuals, earnings reports, and research papers is locked away inside visual formats (tables, graphs, and schematic diagrams). Text-only RAG pipelines discard over a third of a document’s core value proposition.
- Retrieval Precision: By utilizing LLM-generated summaries for vector indexing while preserving high-resolution raster files for final generation, systems avoid the semantic dilution that occurs when attempting to embed raw pixels directly into text embedding spaces.
- Hardware Accessibility: Unlike local, resource-intensive PyTorch implementations that require heavy on-premise GPU clusters for audio-visual processing workloads, API-driven architectures (leveraging managed endpoints like OpenAI and Chroma) democratize access, running comfortably on standard cloud instances or local developer workstations.
Official Statements & Industry Perspective
As artificial intelligence systems evolve from text processors into native multi-modal reasoning engines, industry consensus has solidified around the necessity of holistic document parsing.
According to leading AI research compilations—such as The Multimodal AI Guide—modern enterprise applications can no longer treat vision, voice, and text as isolated silos. State-of-the-art workflows require ingestion pipelines that mirror human reading comprehension: glancing at figures, cross-referencing captions, and reading body text concurrently.
By implementing an API-driven multi-modal RAG pattern, organizations bridge the gap between legacy document layouts and cutting-edge frontier models, ensuring that compliance documents, engineering blueprints, and financial disclosures are understood in their entirety.
Future Outlook & Production Scaling
While the foundational pipeline detailed above successfully resolves the limitations of text-only RAG, production deployments require further refinement and scaling strategies. Developers looking to take this architecture into enterprise production should evaluate the following expansion pathways:
- Advanced Re-Ranking: Incorporate cross-encoder re-rankers (such as Cohere Re-rank or BGE-Reranker) between the retrieval and generation phases to dramatically improve precision and filter out noisy image summaries.
- Persistent Vector Storage: Transition from in-memory and lightweight vector stores to persistent, distributed configurations of Chroma, Pinecone, or Milvus to support millions of enterprise documents across distributed clusters.
- Emerging Native Vision Models: Explore end-to-end vision-language retrieval models like ColPali, which bypass intermediate parsing and summarization steps entirely by directly embedding document pages as multi-vector image tokens.
By embracing multi-modal RAG today, engineering teams ensure their AI applications are fully equipped to navigate the complex, visually rich documents of tomorrow.