Executive Overview
For engineering teams building modern artificial intelligence applications, a familiar scenario plays out weekly: an agile squad drops the pgvector extension into an existing production PostgreSQL instance on a Tuesday afternoon. Relational records and high-dimensional vector embeddings sit side-by-side in a single table, allowing a single SQL query to execute relational filtering and approximate nearest-neighbor similarity searches simultaneously.
Months later, as the dataset scales into millions of records, an enterprise vendor pitch lands in the team’s inbox, insisting that the organization must migrate to a "real" dedicated vector database before hitting an insurmountable architectural wall. Rarely do these pitches—in either direction—accompany their bold claims with empirical data. They rely instead on market momentum, institutional bias, and developer sentiment.
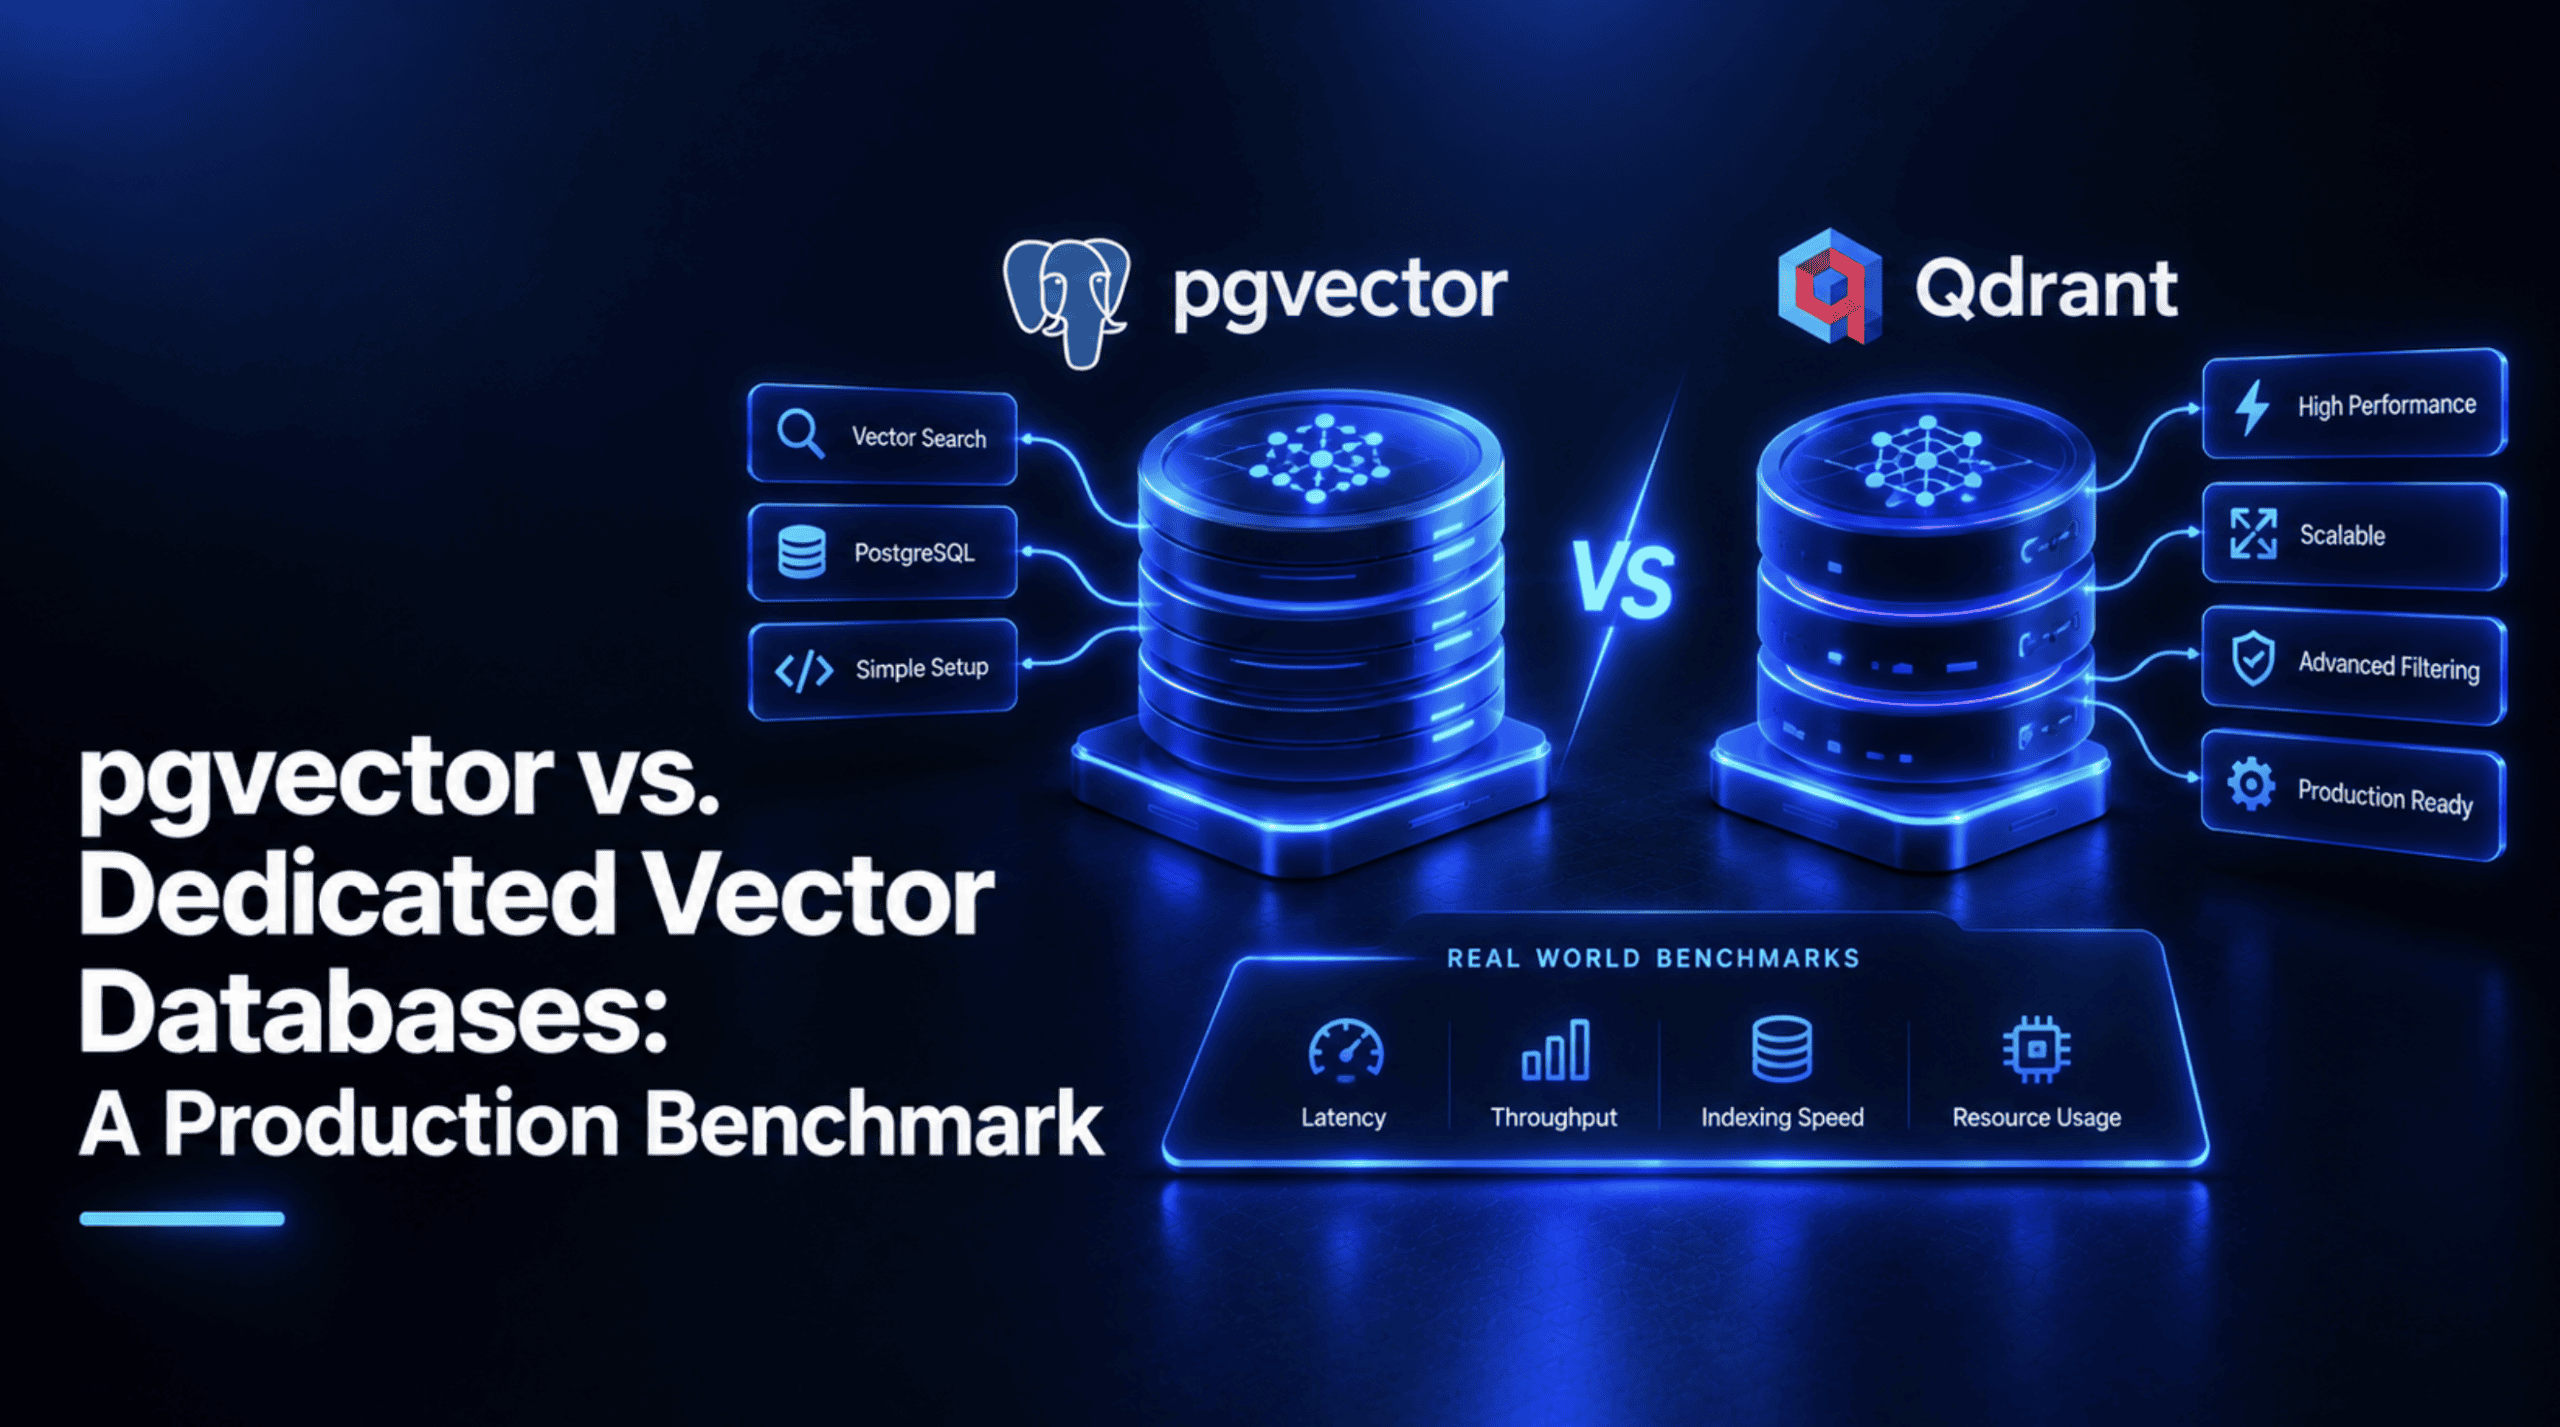
To close this persistent gap between strong opinions and empirical reality, this investigation examines real, measured performance metrics. By testing pgvector against purpose-built alternatives like Qdrant under matched production conditions, we aim to replace vendor-driven speculation with verifiable engineering benchmarks. The results do not support a sweeping narrative. Instead, they reveal a nuanced technical trade-off between transaction simplicity, query throughput, and tail-latency performance.
Detailed Chronology: The Evolution of Vector Search Architecture
The debate between extending a general-purpose relational database and deploying a purpose-built vector engine mirrors historical database debates. When full-text search emerged, developers initially debated whether to use PostgreSQL’s native tsvector types or spin up dedicated search clusters running Elasticsearch or Apache Solr. Similarly, when JSON documents gained prominence, teams weighed native JSONB columns against specialized document stores.
The Rise of Embedded Extensions
The release of pgvector democratized vector embeddings by bringing high-dimensional similarity search directly into the world’s most popular open-source relational database. Rather than introducing a second stateful service, maintaining complex data pipelines, and managing network hops between relational systems and vector stores, developers could treat embeddings as a first-class native data type.
As pgvector matured through successive minor and major versions—culminating in version 0.8.6 and native support within PostgreSQL 13 through 17—it integrated support for advanced indexing algorithms like HNSW (Hierarchical Navigable Small World) and IVFFlat (Inverted File Flat). It also incorporated multiple distance metrics (L2, inner product, cosine, L1, and Hamming) and specialized data types (single-precision, half-precision, binary, and sparse vectors).
The Counter-Revolution of Purpose-Built Engines
Concurrently, dedicated vector databases emerged from the ground up to solve the unique memory, indexing, and distributed consensus challenges of similarity search at planetary scale. Platforms such as Pinecone, Qdrant, Weaviate, Milvus, and ChromaDB were architected specifically around vector operations, leveraging memory-mapped file architectures, custom storage engines, and GPU-accelerated indexing pipelines.
These dedicated systems argued that general-purpose relational databases, constrained by traditional locking mechanisms, buffer management strategies, and concurrency controls, would inevitably buckle under the immense computational weight of billion-scale vector indices.
Supporting Context & Metrics: A Local and Production-Scale Breakdown
To understand how these architectural differences manifest in practice, we must evaluate both local prototyping setups and rigorous, large-scale production benchmarks.
Setting Up the Local Benchmarking Environment
Evaluating pgvector and a dedicated system like Qdrant locally requires a controlled environment. Using Docker and Python 3.10+, we can provision both systems on standard hardware to understand their programmatic interfaces and operational footprints.
Local pgvector Initialization
# docker-compose.yml
services:
  postgres:
    image: pgvector/pgvector:pg17
    ports:
      - "5432:5432"
    environment:
      - POSTGRES_PASSWORD=benchmark
      - POSTGRES_DB=vectorbench
Once running, connecting via Python and establishing the schema requires minimal boilerplate:
import psycopg2
from pgvector.psycopg2 import register_vector

conn = psycopg2.connect(
    host="localhost", port=5432, dbname="vectorbench",
    user="postgres", password="benchmark"
)
conn.autocommit = True
cur = conn.cursor()

# Enable the vector extension
cur.execute("CREATE EXTENSION IF NOT EXISTS vector;")

# Create a table with 1536 dimensions (matching OpenAI's text-embedding-3-small)
cur.execute("""
    CREATE TABLE IF NOT EXISTS items (
        id bigserial PRIMARY KEY,
        embedding vector(1536)
    );
""")
register_vector(conn)
Local Qdrant Initialization
In parallel, Qdrant can be deployed via a single Docker command and configured via its official Python client:
from qdrant_client import QdrantClient
from qdrant_client.models import Distance, VectorParams

qdrant = QdrantClient(url="http://localhost:6333")
qdrant.create_collection(
    collection_name="items",
    vectors_config=VectorParams(size=1536, distance=Distance.COSINE),
)
Generating Synthetic Test Datasets
To ensure a fair comparison, both systems must ingest identical synthetic datasets comprising 100,000 normalized vectors at 1536 dimensions, simulating realistic output from modern embedding models:
import numpy as np

NUM_VECTORS = 100_000
DIM = 1536
rng = np.random.default_rng(seed=42)

vectors = rng.normal(size=(NUM_VECTORS, DIM)).astype(np.float32)
# Normalize vectors to unit length for accurate cosine distance comparison
vectors /= np.linalg.norm(vectors, axis=1, keepdims=True)
Loading these vectors into pgvector via psycopg2.extras.execute_values and into Qdrant in batched PointStruct arrays establishes parallel baselines. Crucially, applying identical HNSW parameters (m = 16, ef_construction = 64) to both systems ensures that any performance variances stem from architectural execution rather than disparate algorithmic configurations.
Production-Scale Performance Analysis
While laptop-based benchmarks are invaluable for validating syntax and operational workflows, they fail to reveal how systems behave under heavy concurrent workloads and massive memory pressures. For true production insights, we must look to large-scale empirical evaluations, such as those published by Tiger Data using 50 million real Cohere embeddings at 768 dimensions on matched AWS hardware (r6id.4xlarge: 16 vCPUs, 128GB RAM).
Note: This specific benchmark evaluated PostgreSQL running pgvector combined with pgvectorscale—an extension providing the StreamingDiskANN index—rather than vanilla pgvector alone.
| Performance Metric | PostgreSQL (pgvector + pgvectorscale) |
Qdrant |
|---|---|---|
| p50 Latency (@ 99% Recall) | 31.07 ms | 30.75 ms |
| p95 Latency (@ 99% Recall) | 60.42 ms | 36.73 ms |
| p99 Latency (@ 99% Recall) | 74.60 ms | 38.71 ms |
| Throughput (@ 99% Recall) | 471.57 QPS | 41.47 QPS |
| p50 Latency (@ 90% Recall) | 9.54 ms | 4.74 ms |
| Throughput (@ 90% Recall) | 1,589.79 QPS | 360.81 QPS |
| Index Build Time (50M Vectors) | 11.1 hours | 3.3 hours |
Analyzing the Trade-Offs
The data demonstrates a clear dichotomy between raw throughput and tail-latency predictability:
- Throughput Advantage for PostgreSQL: At 99% recall, the PostgreSQL-based setup delivered roughly 11.4 times the query throughput of Qdrant (471.57 QPS vs. 41.47 QPS). When recall requirements were relaxed to 90%, PostgreSQL scaled past 1,589 QPS. This exceptional throughput highlights the efficiency of mature relational query planners and connection pooling layers when optimized with modern indexing extensions.
- Tail-Latency Stability for Dedicated Engines: Conversely, Qdrant exhibited superior tail-latency behavior under heavy load. Its p99 latency at 99% recall (38.71 ms) was nearly 48% faster than the PostgreSQL configuration (74.60 ms). For applications bound by stringent SLA constraints where outlier latencies degrade user experience, purpose-built engines maintain tighter operational guardrails.
- Indexing Overhead: Qdrant constructed its 50-million-vector index in 3.3 hours—more than three times faster than the 11.1 hours required by the PostgreSQL extension stack.
Official Statements and Industry Perspectives
Engineering leaders across the database ecosystem emphasize that the choice between extensions and dedicated databases is fundamentally about operational posture and system boundaries.
Database architects maintain that for the vast majority of applications operating below 5 to 10 million vectors, introducing a dedicated vector database introduces unnecessary operational friction. The ability to execute ACID-compliant transactions—updating a core relational business entity and its associated embedding in a single atomic database transaction—eliminates entire classes of distributed data synchronization bugs.
Conversely, maintainers of dedicated vector engines emphasize that as enterprise workloads scale toward hundreds of millions or billions of vectors, specialized memory management, distributed sharding, and native hardware acceleration (such as GPU-assisted index building) become essential. Organizations with dedicated data platform teams are better equipped to absorb the operational overhead of running a secondary polyglot persistence layer.
Future Outlook
As the artificial intelligence landscape matures, the architectural dividing line between relational databases and specialized vector stores is likely to blur further.
We anticipate two primary trajectories:
- The Relational Consolidation: General-purpose relational databases will continue aggressive optimization of vector extension modules, narrowing the tail-latency gap through advanced hardware-intrinsic vector instructions (AVX-512, ARM Neon) and parallelized index scanning.
- The Intelligent Hybridization: Dedicated vector databases will evolve to support richer metadata filtering, transactional semantics, and multi-modal data types, effectively encroaching upon traditional database territory.
For engineering teams today, the decision should not be dictated by marketing trends or dogmatic opposition to extensions. Instead, architecture decisions must be anchored in empirical reality: evaluate your scale, audit your team’s operational bandwidth, measure concurrent query loads, and select the system that aligns with your workload’s actual engineering constraints.