Executive Overview
In enterprise software development and data-heavy machine learning workflows, few failures are as sudden or frustrating as the midnight MemoryError. A script that has operated flawlessly for a year, processing predictable volumes of telemetry or financial transactions, suddenly grinds to a halt. The culprit is rarely a fundamental flaw in the business logic or an unforeseen anomaly in the data itself. Instead, it is an architectural trap rooted in how programming languages handle collections: the default instinct to load entire datasets into RAM all at once.
When log rotation policies shift or upstream data ingest surges—turning a modest 500 MB data feed into a 9 GB monolithic file—traditional "eager" data processing pipelines instantly fail. By accumulating parsed records into standard Python lists before filtering, sorting, or aggregating, applications violate the physical constraints of their host environments.
This article explores how developers can leverage Python’s native iterators, generator functions, and generator expressions to build memory-efficient data processing pipelines. By maintaining a strictly "lazy" data path from the file object at the top of the execution tree down to the batch writer at the bottom, engineers can process datasets of arbitrary scale using minimal, predictable system memory.
Detailed Chronology: The Anatomy of a Memory Failure
To understand the mechanics of streaming data pipelines, we must first examine the pathology of a common production failure. Consider a routine log-summarization script designed to parse application performance metrics:
with open("app.log") as f:
    records = [parse(line) for line in f]      # every record exists at once
errors = [r for r in records if r["level"] == "ERROR"]
slow = [r for r in errors if int(r["latency_ms"]) > 1000]
At first glance, this code appears benign, idiomatic, and clean. Code reviewers would pass it without hesitation. Yet, behind this syntactic elegance lies a severe memory bottleneck.
The Cost of Eager Evaluation
- The First List Comprehension: The execution of
[parse(line) for line in f]forces Python to evaluate the entire file immediately. The list comprehension constructs an in-memory array containing every single parsed record. If the source file is 9 GB, the resulting list consumes substantially more than 9 GB of RAM due to Python’s object overhead and dictionary allocations. - The Subsequent Filters: Once the primary list is fully materialized, the second and third comprehensions generate additional lists (
errorsandslow), further compounding memory pressure.
The Streaming Paradigm Shift
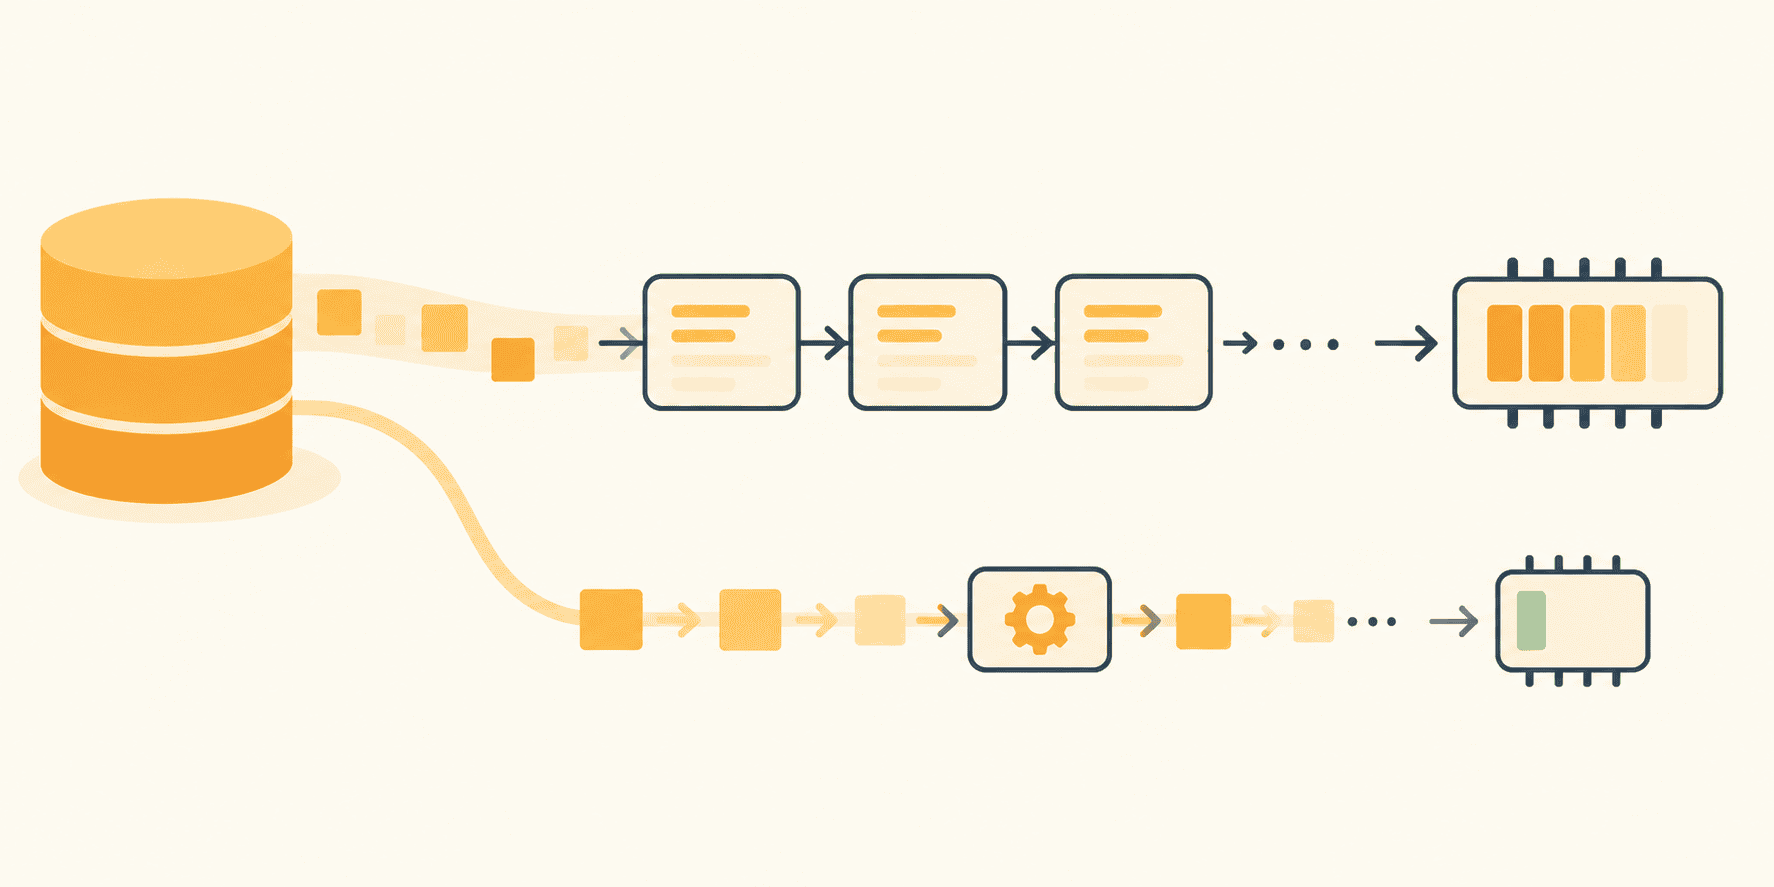
If each step in the processing lifecycle ultimately requires only a single record at a time, forcing every record to exist simultaneously is an anti-pattern. Python has provided the machinery to avoid this for decades through iterators, generator functions, and generator expressions.
A streaming pipeline pulls a single record through every stage of transformation—parsing, filtering, and projecting—and releases it to garbage collection before the next record arrives. However, this strategy requires strict discipline: laziness must be absolute from top to bottom. Introducing a single eager operation (such as calling readlines() or casting a generator to a list()) shatters the pipeline’s memory efficiency and reintroduces the original MemoryError.
Supporting Context & Metrics: Iterables, Generators, and Memory Benchmarks
The Iterator Contract
Underpinning Python’s streaming capabilities is a simple protocol hidden beneath the syntax of the standard for loop:
- Iterables: Objects capable of returning their members one at a time (e.g., lists, strings, dictionaries, open file objects).
- Iterators: Objects that represent a stream of data and maintain state regarding their current position within that stream.
When a loop executes for line in f, Python calls iter(f) once to obtain an iterator, and subsequently invokes next() on that iterator until a StopIteration exception is raised.
numbers = iter([10, 20, 30])
next(numbers)   # 10
next(numbers)   # 20
next(numbers)   # 30
next(numbers)   # raises StopIteration
Crucially, an iterator is a forward-only cursor. It does not duplicate the underlying data structure; it merely tracks position. This single property enables an application to parse a 9 GB file using a small read buffer rather than committing gigabytes of strings to RAM.
Architectural Transformation: Building the Pipeline
To transition from eager evaluation to lazy streaming, we must refactor monolithic scripts into distinct, decoupled generator functions using the yield keyword.
import re

LINE = re.compile(r"^(?P<ts>S+) (?P<level>[A-Z]+) (?P<service>[w-]+)(?P<rest>.*)$")

def read_lines(paths):
    for path in paths:
        with open(path, encoding="utf-8") as f:
            yield from f

def parse_records(lines):
    for line in lines:
        match = LINE.match(line)
        if match is None:
            continue
        record = match.groupdict()
        record["fields"] = dict(
            item.split("=", 1) for item in record.pop("rest").split() if "=" in item
        )
        yield record

def only_level(records, level):
    for record in records:
        if record["level"] == level:
            yield record
The Power of Suspension
When a generator function executes a yield statement, Python suspends execution. All local state—variable bindings, the instruction pointer, and the evaluation stack—is preserved. The function pauses mid-loop, holding precisely one record in scope.
Because the function has not advanced to the next line of the source file, the subsequent record does not yet exist in memory. When the caller requests the next item, execution resumes seamlessly.
Empirical Performance Metrics
To quantify the impact of this architectural shift, comparative benchmarking reveals dramatic divergence in resource consumption:
- Eager Pipeline (using
readlines()and list comprehensions):- Tested against a synthetic 200,000-line log file (~17 MB).
- Peak Memory: ~198 MB.
- Observation: Peak memory scales linearly with file size. Scaling the dataset to 9 GB causes immediate memory exhaustion.
- Lazy Streaming Pipeline (using file iterators and generator functions):
- Tested against the same 200,000-line log file.
- Peak Memory: ~0.4 MB.
- Observation: Peak memory remains constant regardless of file size, scaling only with the size of the output batch.
Using Python’s native tracemalloc module, developers can continuously monitor and verify memory profiles during execution:
import tracemalloc

tracemalloc.start()
write_batches(rows, "slow_errors.tsv")
current, peak = tracemalloc.get_traced_memory()
tracemalloc.stop()

print(f"current current / 1e6:.1f MB, peak peak / 1e6:.1f MB")
Official Statements and Industry Standards
Engineering authorities and core Python documentation emphasize that memory management in data-intensive applications is an explicit design choice rather than an automated feature.

"Iterators provide a unified interface to stream data sequentially without requiring random access or full in-memory materialization. When combined with generator expressions and standard library utilities like
itertools, developers can construct pipelines that handle arbitrarily large datasets with bounded resource footprints." — Python Software Foundation (Core Documentation)
Despite these capabilities, industry practitioners must recognize the boundaries of streaming architectures. Certain algorithmic operations—such as global sorting (sorted()), exact deduplication across an entire dataset, or calculating exact statistical percentiles—fundamentally require complete data visibility.
Attempting to force a streaming pipeline into an inherently non-streaming operation (e.g., piping a lazy generator directly into a sorted() function) secretly reintroduces the exact memory vulnerability the pipeline was designed to eliminate. For such workloads, engineers must rely on external disk-based sorting algorithms or approximate streaming statistical methods (such as HyperLogLog or t-Digest).
Future Outlook: Streaming as an Enterprise Standard
As data volumes across machine learning preprocessing, real-time telemetry, and enterprise logging continue to expand exponentially, the tolerance for inefficient memory usage is vanishing. Eager list-based data ingestion is rapidly becoming obsolete in production environments.
The architectural principles outlined here extend far beyond local log parsing. The same four-stage design pattern—lazy file iteration, parsing generators, filtered generator expressions, and bounded boundary batching—applies directly to:
- Massive CSV exports that exceed spreadsheet memory limits.
- Event telemetry streams pulled from message brokers (e.g., Apache Kafka, RabbitMQ).
- Large JSONL corpora utilized in large language model (LLM) fine-tuning and preprocessing workflows.
By maintaining strict discipline over data boundaries, utilizing modern standard library utilities like itertools.batched() (introduced in Python 3.12), and continuously measuring peak memory allocations via tracemalloc, engineering teams can build resilient, highly scalable data pipelines capable of weathering any data surge.