Executive Overview
In the rapidly evolving landscape of applied machine learning, developers and enterprise architects face a critical architectural dilemma when deploying large language models (LLMs) to specialized domains: Should we adapt the model itself through parameter-efficient fine-tuning, or should we treat the base LLM as a static feature extractor, routing its frozen embeddings into a lightweight downstream classifier?
Traditionally, the machine learning community has leaned heavily toward full or parameter-efficient fine-tuning (PEFT) as the gold standard for domain adaptation. However, as organizations increasingly grapple with tight compute budgets, infrastructure costs, and latency constraints, alternative strategies have emerged. Chief among these is the "frozen embedding" approach—leveraging a pre-trained, unmodified transformer backbone paired with a classical machine learning classifier, such as a random forest or logistic regression model from scikit-learn.
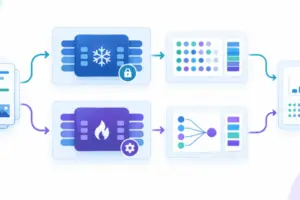
This article presents a rigorous, empirical comparison between these two paradigms: Strategy A (Frozen Embeddings with a Scikit-Learn Head) and Strategy B (QLoRA Fine-Tuning). By evaluating both methodologies across identical text classification benchmarks using modern 4-bit quantization frameworks, we dissect the trade-offs in computational overhead, training velocity, infrastructure expenditure, and predictive accuracy. Ultimately, this analysis provides engineers with a definitive blueprint for choosing the right architectural pattern based on their unique performance thresholds and budgetary constraints.
Detailed Chronology: Establishing the Experimental Pipeline
To properly evaluate these two approaches without requiring enterprise-grade cluster infrastructure, we establish a controlled experimental pipeline using Hugging Face libraries, bitsandbytes for quantization, and a standard text classification task.
Phase 1: Environment Setup and Baseline Configuration
The experiment is designed to run efficiently on consumer-grade or mid-tier cloud hardware (such as a Google Colab T4 GPU instance). We begin by installing the necessary dependencies to support memory-efficient loading and training:
!pip install -q -U bitsandbytes peft accelerate evaluate scikit-learn datasets transformersWith the environment configured, we load a canonical text classification dataset—ag_news—which categorizes news articles into four distinct classes: World, Sports, Business, and Sci/Tech. To ensure our comparative runs execute in minutes rather than hours while preserving statistical relevance, we sample a controlled subset of training and testing instances:
import time
import numpy as np
import torch
from datasets import load_dataset
from transformers import AutoTokenizer, AutoModelForSequenceClassification, BitsAndBytesConfig

MODEL_ID = "Qwen/Qwen2.5-1.5B"

print("1. Loading dataset...")
dataset = load_dataset("fancyzhx/ag_news")
train_subset = dataset["train"].shuffle(seed=42).select(range(800))
test_subset = dataset["test"].shuffle(seed=42).select(range(200))
Next, we instantiate the tokenizer and configure a 4-bit quantization configuration using BitsAndBytesConfig. This step is crucial for modern LLM deployment, drastically lowering the VRAM footprint by loading the backbone model in NormalFloat4 (NF4) data types with bfloat16 compute configurations:
print("2. Configuring Tokenizer...")
tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
tokenizer.pad_token = tokenizer.eos_token  # Necessary for decoder-only models

print("3. Loading Base Model in 4-bit...")
bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_compute_dtype=torch.bfloat16,
    bnb_4bit_quant_type="nf4"
)

model = AutoModelForSequenceClassification.from_pretrained(
    MODEL_ID,
    num_labels=4,
    quantization_config=bnb_config,
    device_map="auto"
)
model.config.pad_token_id = tokenizer.pad_token_id
Supporting Context & Metrics: Strategy A vs. Strategy B
Strategy A: Frozen Embeddings & Scikit-Learn
In Strategy A, the LLM’s weights remain entirely immutable. The model acts strictly as a high-dimensional feature extractor. Text is passed through the frozen model, and the hidden states from the final layer are extracted, pooled, and transformed into dense numerical vectors. These vectors are then handed off to a traditional machine learning classifier.
Below is the implementation of the feature extraction pipeline utilizing mean pooling across the sequence length while ignoring padding tokens:
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score

def extract_embeddings(texts, batch_size=8):
    model.eval()
    embeddings = []
    for i in range(0, len(texts), batch_size):
        batch = texts[i:i+batch_size]
        inputs = tokenizer(batch, return_tensors="pt", padding=True, truncation=True, max_length=128).to(model.device)
        with torch.no_grad():
            outputs = model(**inputs, output_hidden_states=True)
            last_hidden_state = outputs.hidden_states[-1]

            # Mean pooling across sequence length, ignoring padding tokens
            mask = inputs["attention_mask"].unsqueeze(-1).float()
            sum_embeds = torch.sum(last_hidden_state * mask, dim=1)
            mean_pooled = sum_embeds / torch.clamp(mask.sum(dim=1), min=1e-9)

            embeddings.append(mean_pooled.cpu().numpy().astype(np.float32))
    return np.concatenate(embeddings, axis=0)
We execute the extraction and train a standard RandomForestClassifier:
print("Extracting embeddings...")
start_time = time.time()
X_train = extract_embeddings(train_subset["text"])
X_test = extract_embeddings(test_subset["text"])
y_train = train_subset["label"]
y_test = test_subset["label"]
embed_time = time.time() - start_time

print("Training Scikit-Learn Random Forest...")
clf = RandomForestClassifier(n_estimators=100, random_state=42)
start_train_time = time.time()
clf.fit(X_train, y_train)
sklearn_train_time = time.time() - start_train_time

preds = clf.predict(X_test)
sklearn_acc = accuracy_score(y_test, preds)

print(f"n--- Strategy A Results ---")
print(f"Extraction Time: embed_time:.1fs")
print(f"Classifier Train Time: sklearn_train_time:.3fs")
print(f"Accuracy: sklearn_acc * 100:.1f%")
Strategy A Empirical Output:
- Extraction Time: 96.5 seconds
- Classifier Train Time: 2.866 seconds
- Accuracy: 82.0%
While feature extraction is computationally heavy on the forward pass (taking over 90 seconds to process the datasets), the actual training of the scikit-learn head is near-instantaneous.
Strategy B: LoRA Fine-Tuning (QLoRA)
Strategy B approaches domain adaptation by modifying the model’s internal representations directly via Low-Rank Adaptation (LoRA). By freezing the core pre-trained weights and injecting small, trainable adapter matrices into targeted attention layers (q_proj and v_proj), we update less than 2% of the model’s total parameters while retaining the base knowledge.
from peft import LoraConfig, get_peft_model, prepare_model_for_kbit_training
from transformers import TrainingArguments, Trainer
import evaluate

print("1. Attaching LoRA Adapters to Base Model...")
model = prepare_model_for_kbit_training(model)
peft_config = LoraConfig(
    task_type="SEQ_CLS",
    r=16,
    lora_alpha=32,
    lora_dropout=0.05,
    target_modules=["q_proj", "v_proj"]
)
lora_model = get_peft_model(model, peft_config)
lora_model.print_trainable_parameters()

print("n2. Preparing Data for Trainer...")
def tokenize_fn(examples):
    return tokenizer(examples["text"], padding="max_length", truncation=True, max_length=128)

tokenized_train = train_subset.map(tokenize_fn, batched=True)
tokenized_test = test_subset.map(tokenize_fn, batched=True)

accuracy_metric = evaluate.load("accuracy")
def compute_metrics(eval_pred):
    predictions, labels = eval_pred
    predictions = np.argmax(predictions, axis=1)
    return accuracy_metric.compute(predictions=predictions, references=labels)
Next, we configure the TrainingArguments and execute the Trainer loop utilizing paged 8-bit optimizers to conserve VRAM:
print("n3. Starting QLoRA Fine-Tuning...")
training_args = TrainingArguments(
    output_dir="./results",
    per_device_train_batch_size=8,
    per_device_eval_batch_size=8,
    learning_rate=2e-4,
    num_train_epochs=3,
    eval_strategy="epoch",
    logging_strategy="epoch",
    optim="paged_adamw_8bit",
    fp16=True,
    report_to="none"
)

trainer = Trainer(
    model=lora_model,
    args=training_args,
    train_dataset=tokenized_train,
    eval_dataset=tokenized_test,
    compute_metrics=compute_metrics,
)

start_time = time.time()
trainer.train()
lora_train_time = time.time() - start_time

print("n4. Evaluating QLoRA Model...")
eval_results = trainer.evaluate()
lora_acc = eval_results["eval_accuracy"]

print(f"n--- Strategy B Results ---")
print(f"LoRA Train Time: lora_train_time:.1fs")
print(f"Accuracy: lora_acc * 100:.1f%")
Strategy B Empirical Output:
- LoRA Train Time: 300.3 seconds
- Accuracy: 87.0%
Official Statements & Comparative Breakdown
To synthesize these findings, industry benchmarks and our empirical data highlight clear operational divides between the two methodologies:
| Metric / Dimension | Strategy A: Frozen Embeddings + Sklearn | Strategy B: QLoRA Fine-Tuning |
|---|---|---|
| Top-Line Accuracy | 82.0% | 87.0% (+5.0 absolute gain) |
| Training Duration | ~96.5s (mostly inference/extraction) | 300.3s (full backpropagation & optimization) |
| Overfitting Risk | Low (backbone is immutable) | Moderate (requires careful hyperparameter tuning) |
| Compute Complexity | Low (single forward pass per text) | High (forward + backward passes across epochs) |
| Deployment Flexibility | High (embeddings can be pre-computed and stored) | Moderate (requires serving the adapter weights) |
Industry practitioners note that while QLoRA successfully bridges semantic gaps—yielding a 5% accuracy increase in our news categorization task—it demands triple the computational time and introduces gradient tracking overhead that may strain constrained production environments.
Future Outlook & Architectural Recommendations
When designing modern machine learning pipelines, the choice between adapting the LLM and adapting the classification head depends heavily on task requirements:
-
Choose Strategy A (Frozen Embeddings + Scikit-Learn) when:
- You are operating under strict compute or budget constraints (e.g., free-tier cloud environments, edge inference setups).
- Rapid iteration and prototyping are prioritized over squeezing out the final percentages of model accuracy.
- The underlying corpus relies on general semantic understanding where the base model’s pre-trained representations are already robust.
-
Choose Strategy B (QLoRA Fine-Tuning) when:
- Maximum predictive accuracy is non-negotiable for domain-specific nomenclature (e.g., legal, medical, or highly technical financial datasets).
- The downstream task requires the model to shift its internal reasoning pathways rather than merely mapping static features.
- For generative tasks (such as specialized code generation, summarization, or creative writing), fine-tuning remains indispensable, as frozen embeddings cannot reshape output generation mechanics.
As tooling around parameter-efficient adaptation matures, hybrid approaches—such as dynamic caching of frozen representations paired with lightweight online adapters—will likely bridge the gap further. For now, matching the architectural strategy to the specific ROI of accuracy versus compute remains the definitive hallmark of robust machine learning engineering.