Executive Overview
The paradigm of Retrieval-Augmented Generation (RAG) has long served as the bedrock for grounding large language models (LLMs) in proprietary or domain-specific corpuses. Traditional RAG architectures excel when processing plain text corpora, seamlessly transforming prose into vectorized embeddings to fetch relevant context for user queries. However, these text-centric pipelines fail catastrophically when confronted with the realities of modern enterprise documentation.
Corporate financial reports, technical whitepapers, research manuscripts, and regulatory filings are rarely monochromatic walls of text. Instead, they are dense, multi-dimensional artifacts rich with embedded data tables, scanned architecture diagrams, infographic flowcharts, and high-stakes financial charts.
When a standard text-based chunking algorithm parses a PDF containing these visual assets, it fundamentally alters the document’s ontology. Tables are flattened into jagged, uninterpretable strings of text, while embedded images are discarded entirely. The resulting vector database is left with an incomplete, fragmented picture of the source material. Consequently, when an engineer queries the system, the generated response is compromised by missing evidentiary data.
Enter Multi-Modal RAG. This advanced architectural pattern reimagines the retrieval pipeline by treating non-textual assets—specifically images, charts, and tables—as first-class retrievable objects.
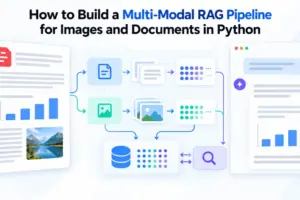
This technical guide details the implementation of a robust, API-driven multi-modal RAG pipeline using Python. Leveraging LangChain, the Unstructured document parsing library, and the OpenAI API (powered by GPT-4o), developers can construct a system that natively parses, summarizes, vectorizes, and reasons across both prose and complex visuals. Designed for standard hardware configurations, this production-ready blueprint bridges the gap between text-centric search and truly comprehensive document intelligence.
Detailed Chronology: Step-by-Step Implementation
To build a multi-modal RAG pipeline capable of reasoning over heterogeneous document elements, developers must execute a precise, four-stage workflow: Parsing, Summarization, Multi-Vector Storage, and Contextual Retrieval.
Prerequisites and Setup
Before writing the application logic, ensure your environment is provisioned with the necessary system dependencies and Python packages. The unstructured library relies heavily on external binaries like poppler-utils to handle rendering and extracting image blocks from PDF files.
pip install langchain langchain-openai unstructured[pdf] chromadb pillow
apt-get install -y poppler-utils
Next, configure your environment to authenticate securely with the OpenAI API:
import os

os.environ["OPENAI_API_KEY"] = "your-api-key-here"
Step 1: Parsing Complex Documents into Text and Image Elements
The foundation of any robust RAG system is its data ingestion engine. Standard PDF loaders strip formatting and ignore graphical assets. To overcome this, we utilize the unstructured library’s partition_pdf() function, which acts as a layout-aware parser. It classifies document components into distinct structural types—separating prose, headers, tables, and embedded images.
from unstructured.partition.pdf import partition_pdf

raw_elements = partition_pdf(
    filename="report.pdf",
    extract_image_block_types=["Image"],
    extract_image_block_output_dir="./extracted_images",
    infer_table_structure=True,
    chunking_strategy="by_title",
    max_characters=4000,
)
In this configuration:
extract_image_block_types=["Image"]instructs the parser to isolate embedded image blocks.extract_image_block_output_dirdesignates the local filesystem directory where extracted PNG assets are stored.infer_table_structure=Truepreserves the relational integrity of data tables.chunking_strategy="by_title"intelligently groups prose based on document hierarchy.
Once partitioning completes, we programmatically separate the raw elements into distinct text and image tracking lists:
text_elements = []
image_paths = []

for el in raw_elements:
    if "CompositeElement" in str(type(el)):
        text_elements.append(str(el))
    elif "Image" in str(type(el)):
        image_paths.append(el.metadata.image_path)

print(f"Extracted len(text_elements) text chunks, len(image_paths) images")
Step 2: Generating Searchable Summaries for Visual Assets
Standard text-based vector databases cannot natively index raw image binaries or interpret pixel arrays via standard semantic distance metrics. To bridge this gap, every extracted image must be assigned a high-fidelity textual proxy—a detailed summary that captures the essence of the graphic, making it discoverable through natural language search queries.
We initialize the OpenAI client and build a summarization routine that encodes each image in base64, dispatching it to GPT-4o with a specialized retrieval prompt:
import base64
from openai import OpenAI

client = OpenAI()

def summarize_image(image_path):
    with open(image_path, "rb") as f:
        image_data = base64.b64encode(f.read()).decode("utf-8")

    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[

                "role": "user",
                "content": [

                        "type": "image_url",
                        "image_url":
                            "url": f"data:image/png;base64,image_data"
                        ,
                    ,

                        "type": "text",
                        "text": "Describe this image in detail for use in a search system.",
                    ,
                ],

        ],
    )
    return response.choices[0].message.content

# Execute the summarization across all discovered image paths
image_summaries = [summarize_image(p) for p in image_paths]
These generated summaries act as searchable proxies. When a user executes a query, the vector database matches against these rich textual descriptions rather than the raw pixels. The source image remains preserved on disk, referenced dynamically when its summary wins the retrieval race.
Step 3: Constructing the Multi-Vector Store Architecture
Standard RAG architectures store text chunks directly in a vector store. Multi-modal architectures require a more sophisticated structure: the MultiVectorRetriever.
This component maintains a decoupled two-tier storage system:
- The Vector Store (
Chroma): Houses the embedded text chunks and the AI-generated image summaries. This store handles high-speed similarity search. - The Document Store (
InMemoryStore): Houses the raw, unadulterated source content (the original text fragments and the absolute paths to the raw image files), linked directly to the vector store via unique identifiers (UUIDs).
import uuid
from langchain.storage import InMemoryStore
from langchain_chroma import Chroma
from langchain_core.documents import Document
from langchain_openai import OpenAIEmbeddings
from langchain.retrievers.multi_vector import MultiVectorRetriever

# Initialize embeddings and storage layers
embeddings = OpenAIEmbeddings(model="text-embedding-3-small")
vectorstore = Chroma(embedding_function=embeddings)
docstore = InMemoryStore()

retriever = MultiVectorRetriever(vectorstore=vectorstore, docstore=docstore)

# Generate unique identifiers for text elements and image summaries
text_ids = [str(uuid.uuid4()) for _ in text_elements]
image_ids = [str(uuid.uuid4()) for _ in image_summaries]
With our storage infrastructure initialized, we populate both layers. The vector store receives the searchable representations (text elements + image summaries), while the document store maps the corresponding IDs directly to the raw source assets:
# Add searchable summaries and texts to the vector store
retriever.vectorstore.add_documents(
    [
        Document(page_content=t, metadata="doc_id": i)
        for t, i in zip(text_elements + image_summaries, text_ids + image_ids)
    ]
)

# Bundle raw text and image paths into Document objects for the docstore
raw_docs = [Document(page_content=t, metadata="type": "text") for t in text_elements] + [
    Document(page_content=p, metadata="type": "image") for p in image_paths
]

# Commit the mappings to the document store
retriever.docstore.mset(list(zip(text_ids + image_ids, raw_docs)))
Step 4: Querying the Pipeline with Multimodal Retrieval
At query time, the retrieval engine embeds the user’s natural language question, queries the Chroma vector store, and returns the highest-scoring matches—regardless of whether those matches originate from a textual paragraph or an image summary.
Once the retriever fetches the relevant nodes from the document store, our execution function inspects their metadata:
def query_pipeline(question):
    docs = retriever.invoke(question)
    text_content, image_content = [], []

    for doc in docs:
        if doc.metadata.get("type") == "image":
            # Load and base64-encode the raw image file on the fly
            with open(doc.page_content, "rb") as f:
                img_b64 = base64.b64encode(f.read()).decode("utf-8")
            image_content.append(

                    "type": "image_url",
                    "image_url": "url": f"data:image/png;base64,img_b64",

            )
        else:
            text_content.append("type": "text", "text": doc.page_content)
The function systematically packages text chunks as text payloads and image paths as base64-encoded image payloads. It then delivers this unified, multi-modal context directly to GPT-4o:
    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[

                "role": "user",
                "content": text_content
                + image_content
                + ["type": "text", "text": question],

        ],
    )
    return response.choices[0].message.content

# Execute a test query against the pipeline
answer = query_pipeline("What does the revenue chart show for Q3?")
print(answer)
Supporting Context & Metrics: Operational Realities
Transitioning a multi-modal RAG architecture from an experimental script to a production service requires careful consideration of operational metrics, cost economics, and system performance.
API Cost and Latency Trade-offs
The primary cost driver in this architecture is the indexing-phase invocation of GPT-4o to generate image summaries.
- Financial Impact: Processing a 100-page corporate financial report containing 45 embedded graphics results in 45 distinct API calls to GPT-4o Vision. While inference costs are negligible for low-volume documents, enterprise environments processing thousands of multi-page technical manuals daily should implement filtering heuristics (e.g., discarding images below a minimum pixel threshold or file size) to prevent runaway API expenditures.
- Indexing Latency: Partitioning complex PDFs with
unstructuredand summarizing visual assets asynchronously can add significant time to the document ingestion pipeline. Implementing a caching layer for already-processed assets is a critical best practice.
Retrieval Precision vs. Recall
By leveraging a MultiVectorRetriever, the system dramatically improves recall for visual data. However, injecting multiple high-resolution images into a single GPT-4o context window can occasionally introduce noise or dilute attention mechanisms. Engineers should tune the k parameter (the number of retrieved documents returned by the vector store) to balance comprehensiveness with token economy.
Official Statements and Architectural Validation
Industry consensus increasingly points toward native multi-modal reasoning as the definitive standard for enterprise search. According to recent research highlighted in advanced artificial intelligence architectural guides, modern LLMs are no longer constrained by modality silos. Text, audio, vision, and tabular data are rapidly converging into unified vector spaces.
As noted by leading machine learning engineering frameworks, traditional pipeline bottlenecks—such as data loss during PDF extraction—represent the single largest point of failure in enterprise generative AI deployments. By treating visual assets with the same semantic gravity as prose, multi-modal RAG architectures solve the "blind spot" problem inherent in legacy text-only implementations.
Future Outlook: The Next Evolution of Document Intelligence
While the API-driven multi-modal RAG pattern detailed here provides an exceptionally stable and accessible foundation for enterprise hardware, the ecosystem continues to evolve at a rapid pace.
- Native Vision-Language Embeddings (ColPali & Beyond): Emerging research models like ColPali bypass the traditional text-summarization bottleneck entirely. Instead of generating descriptive text proxies for images, these models embed raw document pages directly as visual patches, allowing vector stores to execute fine-grained, visual-first similarity searches without intermediary LLM summarization calls.
- Advanced Reranking Integration: Future iterations of this pipeline will incorporate cross-encoder rerankers (such as Cohere Rerank or BGE-Reranker) capable of scoring both text snippets and visual summaries with extreme precision prior to final context assembly.
- Persistent Production Scaling: Transitioning from an in-memory document store (
InMemoryStore) to durable, distributed object storage paired with production-grade vector databases (such as Pinecone, Milvus, or Qdrant persisted to disk) will allow organizations to scale multi-modal search engines to millions of complex corporate documents.
By embracing multi-modal parsing and multi-vector storage today, engineering teams future-proof their AI applications against the inevitable complexity of real-world enterprise data.